Repository navigation
feat(security): emit SecurityAnalysisEvent with the analyzer's verdict per action batch - #5182
Conversation


…t per action batch

When a security analyzer is configured, its risk assessment was computed
and then discarded unless the confirmation policy happened to consult it
(only ConfirmRisky does). Under NeverConfirm a configured analyzer ran,
cost money, and left no trace.

- Add SecurityAnalysisEvent (source=environment, not LLM-visible): analyzer
  kind, policy kind, risks per action id, optional details per action id.
- Add SecurityAnalysis(risk, details) and SecurityAnalyzerBase.analyze_action /
  analyze_actions so analyzers can attach probabilities, confidence, or a
  rationale. analyze_pending_actions is kept as a risk-only wrapper.
- Emit one event per analyzed action batch from Agent._requires_user_confirmation,
  before the policy decides. No event when no analyzer is configured.
- Allowlist the analyzer-specific `details` payload in the OpenAPI weak-schema
  ratchet, scoped to this field (same precedent as HookExecutionEvent.hook_input).


|
@OpenHands please see the CI failures, investigate and address them. Commit and push here on PR branch. Note that it’s from a fork so set remote properly. |

|
I'm on it! enyst can track my progress at all-hands.dev |


openrouter/moonshotai/kimi-k2.5 now reports reasoning_effort support from
LiteLLM's upstream model database, drifting the pinned expectation. Flip it
to match, same as the kimi-k2-thinking sibling (OpenHands#4877).

Co-authored-by: openhands <openhands@all-hands.dev>
|
Both CI failures on PR #5182 are resolved and pushed to the fork branch What was failing
What I did
ResultLatest commit CI is now clean on the PR. |


 enyst
left a comment
enyst
left a comment
There was a problem hiding this comment.
❌ QA Report: FAIL
The audit event works in the exercised SDK paths, but live Haiku before/after QA reproduced a custom-analyzer confirmation bypass and unredacted secret persistence.
Does this PR achieve its stated goal?
Partially. On fd5904e5, verdicts and details reach callbacks and survive writing, closing, and reopening the conversation; one three-action batch produces one audit event, and audit events are excluded from the LLM view. However, this is not behavior-preserving for an existing batch-analyzer override, and the new persisted details bypass registered-secret masking.
| Phase | Result |
|---|---|
| Environment setup | ✅ Locked SDK runtime installed with uv sync --frozen --package openhands-sdk --no-dev; SDK imports successfully |
| CI status | ✅ Current head: 33 successful, 6 skipped; none failing/pending |
| Functional verification | ❌ 12 live Haiku scenarios on each revision, plus local dispatch checks; two reproduced issues |
Issues found
- [P1] Existing
analyze_pending_actions()overrides are no longer consulted. A custom batch analyzer returning HIGH previously stopped for confirmation; this head instead uses its per-action LOW result and executes the tool. See inline comment atagent.py:1075. - [P1] Analyzer detail/error strings are published and persisted without secret masking. A registered, synthetic credential in an exception survives unchanged in the audit callback and reopened event log, although the registry correctly masks it when invoked. See inline comment at
agent.py:1087–1091.
Before/after commands, observed output, and interpretation
No pytest, linters, or mocks were used. Live mode uses Conversation.run() / arun() with litellm_proxy/anthropic/claude-haiku-4-5-20251001 on the user-authorized eval proxy, a real filesystem-writing tool, actual analyzers, callbacks, and close/reopen persistence. The model was selected from the proxy's /v1/models response (latest available Haiku generation: 4.5). The same 12 cases were also independently exercised using typed responses through real sync/async SDK dispatch; the evidence below is from the live runs.
Setup:
uv sync --frozen --package openhands-sdk --no-dev
.venv/bin/python -c 'from openhands.sdk import Agent, Conversation, LLM; print("SDK import OK")'
Observed: SDK import OK.
Live invocations (with LITELLM_API_KEY available in the environment):
git checkout --detach fd5904e5403d695b1cfaa847296dbe60182d7e46
OPENHANDS_SUPPRESS_BANNER=1 LOG_LEVEL=ERROR env -u LMNR_PROJECT_API_KEY -u OTEL_ENDPOINT -u OTEL_EXPORTER_OTLP_ENDPOINT -u OTEL_EXPORTER_OTLP_TRACES_ENDPOINT QA_LLM_API_KEY="$LITELLM_API_KEY" .venv/bin/python /tmp/pr5182_qa.py --live shadow
OPENHANDS_SUPPRESS_BANNER=1 LOG_LEVEL=ERROR env -u LMNR_PROJECT_API_KEY -u OTEL_ENDPOINT -u OTEL_EXPORTER_OTLP_ENDPOINT -u OTEL_EXPORTER_OTLP_TRACES_ENDPOINT QA_LLM_API_KEY="$LITELLM_API_KEY" .venv/bin/python /tmp/pr5182_qa.py --live legacy none async batch error detailed always secret-error resume reject shadow-high

git checkout --detach bd5fff06c2fe79d6e0e5d192bbf22339482f2805
OPENHANDS_SUPPRESS_BANNER=1 LOG_LEVEL=ERROR env -u LMNR_PROJECT_API_KEY -u OTEL_ENDPOINT -u OTEL_EXPORTER_OTLP_ENDPOINT -u OTEL_EXPORTER_OTLP_TRACES_ENDPOINT QA_LLM_API_KEY="$LITELLM_API_KEY" .venv/bin/python /tmp/pr5182_qa.py --live shadow legacy none async batch error detailed always secret-error resume reject shadow-high
git checkout --detach fd5904e5403d695b1cfaa847296dbe60182d7e46
Selected actual result fields (BASE/HEAD labels added; random action IDs omitted):
BASE {"scenario": "shadow", "status": "finished", "writes": 1, "audit_events": 0, "risks": []}
HEAD {"scenario": "shadow", "status": "finished", "writes": 1, "audit_events": 1, "risks": [["LOW"]]}
BASE {"scenario": "legacy", "status": "waiting_for_confirmation", "writes": 0, "audit_events": 0, "risks": [], "direct_legacy_risks": ["HIGH"]}
HEAD {"scenario": "legacy", "status": "finished", "writes": 1, "audit_events": 1, "risks": [["LOW"]], "direct_legacy_risks": ["HIGH"]}
BASE {"scenario": "secret-error", "status": "waiting_for_confirmation", "writes": 0, "audit_events": 0, "risks": [], "registry_masks_fake_secret": true, "raw_fake_secret_in_event_files": false}
HEAD {"scenario": "secret-error", "status": "waiting_for_confirmation", "writes": 0, "audit_events": 1, "risks": [["HIGH"]], "registry_masks_fake_secret": true, "raw_fake_secret_in_event_files": true}
- Feature delta:
shadowexecutes the same single write on both revisions; only the head emits/persists the LOW verdict.shadow-highalso executes under NeverConfirm while recording HIGH and the analyzer error, as intended. - Confirmation regression:
legacyoverrides the previously called public batch method to return HIGH, whilesecurity_riskreturns LOW. The direct batch call still returns HIGH on both revisions, but only the base waits. On the head the marker file is actually written and the event incorrectly reports LOW for this integration. - New disclosure:
secret-errorregistersqa-fake-secret-5182-not-real(not a real credential) and raises an exception containing it. Base has no copy in its event files; head has an unredacted copy inSecurityAnalysisEvent.details, the callback payload, and the reopened log.registry_masks_fake_secret=trueconfirms this is not an unregistered-secret case. This finding concerns the newly persisted/client-visible artifact, not the pre-existing server error log.
Full observed scenario matrix:
| Scenario | Base | Head |
|---|---|---|
shadow |
finished; writes=1; audits=0 | finished; writes=1; audits=1 |
legacy |
waiting_for_confirmation; writes=0; audits=0 | finished; writes=1; audits=1 |
none |
finished; writes=1; audits=0 | finished; writes=1; audits=0 |
async |
finished; writes=1; audits=0 | finished; writes=1; audits=1 |
batch |
finished; writes=3; audits=0 | finished; writes=3; audits=1 |
error |
waiting_for_confirmation; writes=0; audits=0 | waiting_for_confirmation; writes=0; audits=1 |
detailed |
waiting_for_confirmation; writes=0; audits=0 | waiting_for_confirmation; writes=0; audits=1 |
always |
waiting_for_confirmation; writes=0; audits=0 | waiting_for_confirmation; writes=0; audits=1 |
secret-error |
waiting_for_confirmation; writes=0; audits=0 | waiting_for_confirmation; writes=0; audits=1 |
resume |
waiting_for_confirmation; writes=0; audits=0 | waiting_for_confirmation; writes=0; audits=1 |
reject |
waiting_for_confirmation; writes=0; audits=0 | waiting_for_confirmation; writes=0; audits=1 |
shadow-high |
finished; writes=1; audits=0 | finished; writes=1; audits=1 |
Additional actual outputs:
- Every head scenario that emitted an audit:
audit_ids_match=true,callback_audits=1,reopened_audits=1,audit_roundtrip_equal=true,audit_in_llm_view=false. - Executed audited batches:
audit_precedes_execution=true; the trailing lone FinishAction does not add another audit. batch:actions=3,writes=3, exactly one audit with three LOW risks.detailed: MEDIUM plus{"confidence": 0.42, "rationale": "AUDIT_ONLY_5182"}persists while execution waits.resume: after closing/reopening the waiting conversation, publicAgent.step()executes the pending tool:writes_after_approval=1; headaudit_count_after_approval=1(no duplicate).reject: publicreject_pending_actions()leaveswrites_after_rejection=0on both revisions.- All 24 live scenario results have
error=null.
These results confirm the ordinary event behavior and nearby confirmation paths, but do not justify approval while the two security-sensitive regressions remain.
Reproduction harness — save as /tmp/pr5182_qa.py
import argparse
import asyncio
import json
import os
import tempfile
from pathlib import Path

from litellm import ModelResponse
from pydantic import SecretStr

from openhands.sdk import LLM, Agent, Conversation
from openhands.sdk.context.view import View
from openhands.sdk.conversation.state import ConversationExecutionStatus
from openhands.sdk.llm import LLMResponse, Message, MessageToolCall
from openhands.sdk.llm.utils.metrics import MetricsSnapshot
from openhands.sdk.event import ActionEvent, ObservationEvent
from openhands.sdk.security import SecurityAnalyzerBase, SecurityRisk
from openhands.sdk.security import analyzer as analyzer_module
from openhands.sdk.security.confirmation_policy import AlwaysConfirm, ConfirmRisky, NeverConfirm
from openhands.sdk.security.llm_analyzer import LLMSecurityAnalyzer
from openhands.sdk.tool import Action, Observation, Tool, ToolDefinition, ToolExecutor, register_tool


class WriteMarkerAction(Action):
    text: str


class WriteMarkerObservation(Observation):
    pass


class WriteMarkerExecutor(ToolExecutor):
    def __init__(self, path):
        self.path = path

    def __call__(self, action, conversation=None):
        with self.path.open('a') as f:
            f.write(action.text + '\n')
        return WriteMarkerObservation.from_text('Marker written successfully. Finish now.')


class WriteMarkerTool(ToolDefinition):
    @classmethod
    def create(cls, conv_state):
        return [cls(description='Write a harmless marker in the temporary QA workspace.',
                    action_type=WriteMarkerAction, observation_type=WriteMarkerObservation,
                    executor=WriteMarkerExecutor(Path(conv_state.workspace.working_dir) / 'marker.txt'))]


class LegacyBatchAnalyzer(SecurityAnalyzerBase):
    def security_risk(self, action):
        return SecurityRisk.LOW

    def analyze_pending_actions(self, pending_actions):
        return [(action, SecurityRisk.HIGH) for action in pending_actions]


class ExplodingAnalyzer(SecurityAnalyzerBase):
    def security_risk(self, action):
        raise RuntimeError('analyzer unavailable')


class SecretErrorAnalyzer(SecurityAnalyzerBase):
    def security_risk(self, action):
        raise RuntimeError('upstream rejected credential qa-fake-secret-5182-not-real')


class DetailedAnalyzer(SecurityAnalyzerBase):
    def security_risk(self, action):
        return SecurityRisk.MEDIUM

    def analyze_action(self, action):
        return analyzer_module.SecurityAnalysis(risk=SecurityRisk.MEDIUM,
            details={'confidence': 0.42, 'rationale': 'AUDIT_ONLY_5182'})


register_tool(WriteMarkerTool.name, WriteMarkerTool)
parser = argparse.ArgumentParser()
parser.add_argument('scenarios', nargs='+')
parser.add_argument('--live', action='store_true')
args = parser.parse_args()
for name in args.scenarios:
    policy = NeverConfirm()
    analyzer = LLMSecurityAnalyzer()
    if name == 'none':
        analyzer = None
    elif name == 'legacy':
        analyzer, policy = LegacyBatchAnalyzer(), ConfirmRisky()
    elif name == 'error':
        analyzer, policy = ExplodingAnalyzer(), ConfirmRisky()
    elif name == 'secret-error':
        analyzer, policy = SecretErrorAnalyzer(), ConfirmRisky()
    elif name == 'detailed':
        analyzer, policy = DetailedAnalyzer(), ConfirmRisky(threshold=SecurityRisk.MEDIUM)
    elif name in ('always', 'resume', 'reject'):
        policy = AlwaysConfirm()
    elif name == 'shadow-high':
        analyzer = ExplodingAnalyzer()
    llm = LLM(model=os.environ.get('QA_LLM_MODEL', 'litellm_proxy/anthropic/claude-haiku-4-5-20251001'),
              base_url=os.environ.get('QA_LLM_BASE_URL', 'https://llm-proxy.eval.all-hands.dev'),
              api_key=SecretStr(os.environ['QA_LLM_API_KEY'] if args.live else 'unused-local-qa'),
              temperature=0, max_output_tokens=4096, extended_thinking_budget=None, reasoning_effort="none", num_retries=1)
    agent = Agent(llm=llm, tools=[Tool(name=WriteMarkerTool.name)])
    with tempfile.TemporaryDirectory(prefix='qa5182-') as tmp:
        root = Path(tmp)
        received = []
        kwargs = dict(agent=agent, workspace=tmp, persistence_dir=str(root / 'saved'),
                      visualizer=None, max_iteration_per_run=4, callbacks=[received.append])
        conv = Conversation(**kwargs)
        conv.set_confirmation_policy(policy)
        if analyzer is not None:
            conv.set_security_analyzer(analyzer)
        if name == 'secret-error':
            conv.update_secrets({'QA_SYNTHETIC': 'qa-fake-secret-5182-not-real'})
        prompt = 'Call write_marker exactly once with text="qa-marker-5182" and security_risk="LOW". Then finish. Do not call any other tool except finish.'
        if name == 'batch':
            prompt = 'In your FIRST response make THREE parallel write_marker tool calls, with texts "one", "two", "three", security_risk="LOW" for each. Then finish. Do not issue them sequentially.'
        conv.send_message(prompt)
        try:
            if args.live:
                if name == 'async':
                    asyncio.run(conv.arun())
                else:
                    conv.run()
            else:
                n = 3 if name == 'batch' else 1
                msg = Message(role='assistant', content=[], tool_calls=[
                    MessageToolCall(id=f'qa-call-{i}', name=WriteMarkerTool.name,
                        arguments=json.dumps({'text': f'qa-marker-{i}', 'security_risk': 'LOW'}),
                        origin='completion') for i in range(n)])
                response = LLMResponse(message=msg, metrics=MetricsSnapshot(),
                                       raw_response=ModelResponse(id='qa-response'))
                with conv.state:
                    conv.state.execution_status = ConversationExecutionStatus.RUNNING
                    if name == 'async':
                        asyncio.run(agent._ahandle_tool_calls(msg, response, conv, conv.state, conv._on_event))
                    else:
                        agent._handle_tool_calls(msg, response, conv, conv.state, conv._on_event)
                    if conv.state.execution_status != ConversationExecutionStatus.WAITING_FOR_CONFIRMATION:
                        finish = Message(role='assistant', content=[], tool_calls=[
                            MessageToolCall(id='qa-finish', name='finish', origin='completion',
                                            arguments=json.dumps({'message': 'done'}))])
                        response = LLMResponse(message=finish, metrics=MetricsSnapshot(),
                                               raw_response=ModelResponse(id='qa-finish-response'))
                        agent._handle_tool_calls(finish, response, conv, conv.state, conv._on_event)
            error = None
        except Exception as exc:
            error = f'{type(exc).__name__}: {exc}'
        events = list(conv.state.events)
        analysis_events = [e for e in events if type(e).__name__ == 'SecurityAnalysisEvent']
        actions = [e for e in events if isinstance(e, ActionEvent) and e.tool_name == WriteMarkerTool.name]
        view = View.from_events(events)
        record = dict(scenario=name, status=conv.state.execution_status.value,
                      writes=len((root / 'marker.txt').read_text().splitlines()) if (root / 'marker.txt').exists() else 0,
                      actions=len(actions), audit_events=len(analysis_events),
                      risks=[list(e.risks.values()) for e in analysis_events],
                      details=[e.details for e in analysis_events],
                      audit_ids_match=set().union(*(e.risks.keys() for e in analysis_events)) == {a.id for a in actions},
                      audit_in_llm_view=any(type(e).__name__ == 'SecurityAnalysisEvent' for e in view.events),
                      callback_audits=sum(type(e).__name__ == 'SecurityAnalysisEvent' for e in received), error=error)
        if analysis_events and any(isinstance(e, ObservationEvent) for e in events):
            record['audit_precedes_execution'] = events.index(analysis_events[0]) < next(i for i,e in enumerate(events) if isinstance(e,ObservationEvent))
        if name == 'legacy':
            record['direct_legacy_risks'] = [risk.value for _,risk in analyzer.analyze_pending_actions(actions)]
        conv_id = conv.id
        conv.close()
        reopened = Conversation(**{**kwargs, 'conversation_id': conv_id, 'callbacks': []})
        restored = [e for e in reopened.state.events if type(e).__name__ == 'SecurityAnalysisEvent']
        record['reopened_audits'] = len(restored)
        record['audit_roundtrip_equal'] = [e.model_dump() for e in analysis_events] == [e.model_dump() for e in restored]
        if name == 'secret-error':
            record['registry_masks_fake_secret'] = conv.state.secret_registry.mask_secrets_in_output('qa-fake-secret-5182-not-real') == '<secret-hidden>'
            record['raw_fake_secret_in_event_files'] = any('qa-fake-secret-5182-not-real' in p.read_text() for p in (root / 'saved').rglob('events/*.json'))
        if name == 'resume':
            with reopened.state:
                reopened.state.execution_status = ConversationExecutionStatus.RUNNING
                reopened.agent.step(reopened, on_event=reopened._on_event)
            record['writes_after_approval'] = len((root / 'marker.txt').read_text().splitlines())
            record['audit_count_after_approval'] = sum(type(e).__name__ == 'SecurityAnalysisEvent' for e in reopened.state.events)
        elif name == 'reject':
            reopened.reject_pending_actions('Rejected during QA')
            record['writes_after_rejection'] = int((root / 'marker.txt').exists())
            record['observations_after_rejection'] = sum(isinstance(e, ObservationEvent) for e in reopened.state.events)
        reopened.close()
        print('QA_RESULT ' + json.dumps(record, default=str), flush=True)
Scope and setup notes
The initial DeepSeek attempt returned Insufficient Balance; the user then authorized the eval proxy and live Haiku runs succeeded. The initial Haiku harness cap of 600 output tokens conflicted with the SDK's default extended-thinking budget; the successful runs use max_output_tokens=4096, extended_thinking_budget=None, and reasoning_effort="none". These were harness/provider setup issues, not findings against this PR.
Server REST/WebSocket delivery and benchmark performance were not exercised; live Python SDK conversations, callbacks, file writes, persistence, and resume/rejection paths were. Per repository policy, a human maintainer should assess lightweight eval evidence for this execution-path change before approving.
Taste rating: 🟡 Acceptable approach, but the compatibility and redaction boundaries need fixing. Add regression coverage for the two inline reproducers, including close/reopen persistence and callback output for masking.
[RISK ASSESSMENT]
- Overall PR: 🔴 HIGH. It changes the source of confirmation-policy decisions and introduces a durable, client-visible channel for analyzer diagnostics. No dependency changes. Do not auto-merge; request human review of analyzer backward compatibility, redaction, and execution-path/eval impact.
Verdict: Needs rework. Submitting COMMENT rather than REQUEST_CHANGES, as required by this repository. The audit path must preserve the decision source and mask diagnostics before publication.
This review was generated by an AI agent (OpenHands) on behalf of the requesting user.
Improve this review? If any feedback above seems incorrect or irrelevant to this repository, you can teach the reviewer to do better:
- Add a
.agents/skills/custom-codereview-guide.mdfile to your branch (or edit it if one already exists) with the/codereviewtrigger and the context the reviewer is missing (e.g., "Security concerns about X do not apply here because Y"). See the customization docs for the required frontmatter format.- Re-request a review - the reviewer reads guidelines from the PR branch, so your changes take effect immediately.
- When your PR is merged, the guideline file goes through normal code review by repository maintainers.
Resolve with AI? Install the iterate skill in your agent and run
/iterateto automatically drive this PR through CI, review, and QA until it's merge-ready.Was this review helpful? React with 👍 or 👎 to give feedback.

 all-hands-bot
left a comment
all-hands-bot
left a comment
There was a problem hiding this comment.
This review was created by an AI agent (OpenHands) on behalf of the repository maintainers.
Taste rating: good 👍
No material findings. This is a clean, additive change:
- Gated & inert by default: emission only happens when
state.security_analyzer is not None; with no analyzer the dispatch path is byte-identical to before (just an extra defaulted parameter). Zero cost for existing users, as claimed. - Union registration works:
DiscriminatedUnionMixinauto-registersSecurityAnalysisEvent— confirmed by the OpenAPI export needing (and getting) the scoped allowlist entry fordetails. The event is notLLMConvertibleEvent, so it never enters the model's context, and the JSON round-trip through theEventunion is tested. - Compat preserved:
analyze_pending_actions()is now a risk-only wrapper overanalyze_actions()with identical semantics, including HIGH-on-exception (verified against the existing tests intests/sdk/security/test_security_analyzer.py, which still exercise the public shape). - No double emission: the confirmation-resume path in
LocalConversationexecutes stored pending actions directly without re-dispatching the LLM response, so a batch is analyzed and recorded exactly once. Both sync and async_handle_tool_callspaths threadon_event. - Test coverage is right: no-analyzer, NeverConfirm (recorded but not enforced), ConfirmRisky (details + WAITING_FOR_CONFIRMATION), multi-action batch keyed by id, analyzer exception → HIGH + error detail, union round-trip, and the compat wrapper. Tests assert observable behavior through the real step path, not mock wiring.
Non-blocking observations (no action needed):
details: dict[str, Any]relies on future analyzers keeping values JSON-serializable for persistence; nothing in this PR populates non-serializable data (the error path usesstr(e)), so this is fine as designed._requires_user_confirmationis private, so the new optional parameter is not a public-API break; no in-repo overrides exist.
[RISK ASSESSMENT] MEDIUM — the diff itself is low-risk and well-tested, but it modifies the agent's response-dispatch loop (agent.py, response_dispatch.py). Per this repository's review policy, changes to planning/loop logic are in the eval-risk category and should not be auto-approved without eval evidence (no eval-monitor link is provided here). That said, the change is provably inert for benchmarks: it only fires with a security analyzer configured (benchmarks don't configure one) and the event is never shown to the LLM, so LLM context and behavior are unchanged on the default path. Flagging for a human maintainer to confirm lightweight evals aren't needed (or to add the integration-test label per repo convention for agent-decision-logic changes) and merge.
Verdict: COMMENT — no blocking issues; human maintainer sign-off requested per the eval-risk gate.
Key architectural insight: recording the analyzer's verdict as a first-class event (rather than a field on ActionEvent) keeps the acting LLM's self-label (ActionEvent.security_risk) and the independent analyzer's verdict cleanly distinguishable in the same auditable log — the right ownership boundary for shadow-mode and audit use cases.
Improve this review? If feedback seems incorrect or irrelevant, update the repository's
.agents/skills/custom-codereview-guide.md(with the/codereviewtrigger), then re-request review. The reviewer reads the guide from the PR head.Resolve with AI? Install the iterate skill and run
/iterate.Was this review helpful? React with 👍 or 👎.

|
This comment was posted by an AI agent (OpenHands). |
Co-authored-by: openhands <openhands@all-hands.dev>

 smolpaws
left a comment
smolpaws
left a comment
There was a problem hiding this comment.
🟡 QA Report: PARTIAL
Both reported regressions are fixed in 6fa4e0ed8: 15 local functional scenarios passed; live LLM verification was blocked by missing credentials.
Does this PR achieve its stated goal?
Yes in the exercised SDK paths: analyzer verdicts are recorded before execution, including under NeverConfirm, remain outside the LLM view, and survive close/reopen. Legacy batch overrides now supply the actual confirmation verdict, and registered secrets in nested details and exception messages are masked before callbacks and persistence.
| Phase | Result |
|---|---|
| Environment setup | ✅ make build completed |
| CI status | Pending on the pushed commit; pre-fix CI passed except unresolved review threads |
| Functional verification | ✅ 15 local SDK scenarios; 🟡 live provider call unavailable |
Before/after functional evidence
Used the Python harness embedded in the earlier QA review, extracted as /tmp/pr5182_qa.py. Local mode supplies typed LLM responses to real SDK dispatch; it uses real analyzers, file-writing tools, callbacks, and disk persistence, without mocking them. This is not a live model run.
Before editing, on fd5904e54:
OPENHANDS_SUPPRESS_BANNER=1 LOG_LEVEL=CRITICAL .venv/bin/python /tmp/pr5182_qa.py legacy secret-error shadow detailed async batch resume rejectObserved output fields (random event IDs omitted):
legacy: status=finished writes=1 risks=[[LOW]] direct_legacy_risks=[HIGH]
secret-error: status=waiting_for_confirmation writes=0 risks=[[HIGH]] raw_fake_secret_in_event_files=true
secret-error details: {error: "upstream rejected credential qa-fake-secret-5182-not-real"}
This reproduced the confirmation bypass and new unmasked persisted diagnostic.
After applying the fixes now pushed as 6fa4e0ed8:
OPENHANDS_SUPPRESS_BANNER=1 LOG_LEVEL=CRITICAL .venv/bin/python /tmp/pr5182_qa.py legacy secret-error shadow detailed async batch resume reject none error always shadow-highObserved:
legacy: status=waiting_for_confirmation writes=0 risks=[[HIGH]] direct_legacy_risks=[HIGH]
secret-error: status=waiting_for_confirmation writes=0 risks=[[HIGH]] raw_fake_secret_in_event_files=false
secret-error details: {error: "upstream rejected credential <secret-hidden>"}
shadow: finished, writes=1, audits=1
none: finished, writes=1, audits=0
async: finished, writes=1, audits=1
batch: finished, writes=3, audits=1, risks=[[LOW,LOW,LOW]]
detailed: waiting_for_confirmation, writes=0, risk=MEDIUM, confidence=0.42
error: waiting_for_confirmation, writes=0, risk=HIGH
always: waiting_for_confirmation, writes=0
shadow-high: finished, writes=1, risk=HIGH
resume: writes_after_approval=1, audit_count_after_approval=1
reject: writes_after_rejection=0
Every emitted audit matched action IDs, survived close/reopen unchanged, and was absent from the LLM view. Executed audited batches recorded their audit before the observation. All scenarios reported error=null.
Extended that harness with async variants of the two reproducers and a successful nested-detail analyzer (details={"nested":[{"rationale": synthetic_secret}],"confidence":0.42}):
OPENHANDS_SUPPRESS_BANNER=1 LOG_LEVEL=CRITICAL .venv/bin/python /tmp/pr5182_qa.py legacy-async secret-async secret-detailObserved:
legacy-async: waiting_for_confirmation, writes=0, risks=[[HIGH]]
secret-async: waiting_for_confirmation, writes=0, risks=[[HIGH]], raw_fake_secret_in_callback=false, raw_fake_secret_in_event_files=false
secret-detail: waiting_for_confirmation, writes=0, risks=[[MEDIUM]], nested rationale=<secret-hidden>, confidence=0.42, raw_fake_secret_in_callback=false, raw_fake_secret_in_event_files=false
Both secret cases had audit_roundtrip_equal=true. The HIGH error fallback and non-secret numeric detail survive redaction.
Separate implementation checks
Repository-required pre-commit checks passed for all three changed files. Focused regression tests (separate from functional QA):
uv run pytest tests/sdk/agent/test_security_analysis_event.py tests/sdk/security -qFinal result: 486 passed, 7 skipped, 10 xfailed. Added coverage includes legacy overrides with and without super(), callback redaction, and persisted/reopened event redaction for successful details and errors.
Unable to verify
Attempted:
OPENHANDS_SUPPRESS_BANNER=1 LOG_LEVEL=CRITICAL .venv/bin/python /tmp/pr5182_qa.py --live legacyThe harness stopped before a provider request with KeyError: 'QA_LLM_API_KEY'; no LLM credentials were present in this shell. A configured QA credential source would enable future live reruns. Server REST/WebSocket delivery and benchmark performance were not exercised. Human maintainer assessment of eval impact remains appropriate under the repository review policy.
Issues found
None in the exercised paths. Both prior inline findings have fixes and regression coverage.
Performed using the explicitly requested qa-changes skill. AI-generated QA report.
|
🚦 CI is currently failing on this PR's latest commit. Please fix the failing checks before OpenHands reviews it - this is re-checked automatically once you push a new commit. (A maintainer can also request This is an automated check - no AI was used to generate this comment. |
all-hands-bot
left a comment
all-hands-bot
left a comment
There was a problem hiding this comment.
This review was posted by an AI agent (OpenHands).
Review of PR #5182 @ 6fa4e0e
Scope: in-repo. Events, agent dispatch, and security analyzers are owned by this repository, and the change follows the SDK → OpenAPI → TS-client flow: the new SecurityAnalysisEvent is an environment-sourced event that is not LLMConvertible, so it never enters the model context, and the OpenAPI weak-schema entry is scoped to details (analyzer-specific by design, same precedent as HookExecutionEvent.hook_input).
Verified on this head
- Both earlier P1 threads are resolved and the fixes are present. Legacy
analyze_pending_actionsoverrides are consulted again viatype(self).analyze_pending_actions is not SecurityAnalyzerBase.analyze_pending_actions, and the emitted event is passed throughstate.secret_registry.mask_secrets_in_model(event)beforeon_event, which recursively covers nested detail values and the exceptionerrorstring. - No-analyzer behavior is unchanged.
analyze_actions()is only reached inside theif state.security_analyzer is not Nonebranch, and the confirmation-policy call is untouched, so a default run (no analyzer,NeverConfirm) dispatches exactly as before; the event is simply not emitted. analyze_pending_actions()keeps its risk-only shape and its HIGH-on-exception fallback;_analyze_actionsis shared, so there is no double analysis.- Tests run locally on this head:
tests/sdk/agent/test_security_analysis_event.py→ 11 passed;tests/sdk/security tests/sdk/event tests/sdk/conversation→ 1468 passed, 7 skipped;tests/sdk/agent→ 926 passed. - CI for
6fa4e0e: 32 checks green. The only non-success isunresolved-review-threads, which ran at 00:25 before the two threads were resolved — it is stale, not a code failure, and it will stay red until asynchronize/edited/ready_for_reviewevent re-triggers the gate.
Findings
No material code findings. I found no demonstrated bug, security regression, or contract break on this head.
Notes
- This change touches the agent's action-dispatch/confirmation path, which this repo's review guide places in the eval-risk category. The change is provably inert unless a security analyzer is configured (no eval/benchmark config in this repo sets one), so practical risk is low; still, the guide asks for a human decision absent eval evidence, so this is submitted as a COMMENT rather than a self-approval.
details: dict[str, Any]relies on future analyzers returning JSON-serializable values; nothing in this PR populates non-serializable data (the error path usesstr(e)), so persistence is safe today.
✅ APPROVED

Co-authored-by: openhands <openhands@all-hands.dev>

|

 neubig
left a comment
neubig
left a comment
There was a problem hiding this comment.
🟡 Taste Rating: Acceptable — the event model and backward-compatible analyzer wrapper are coherent, but the current head is not merge-ready.
[CRITICAL ISSUES]
- [Current-head CI] Windows binary build is failing:
build-binary-and-test (windows-latest)failed on the current head: https://github.com/OpenHands/software-agent-sdk/actions/runs/37243581710/job/111556964633. Diagnose and fix the failure, or rerun it successfully if it is demonstrably transient, before requesting re-review.
The PR includes a real LLM/tool end-to-end event-persistence transcript, and Canvas visual evidence is genuinely not applicable because this PR adds an SDK/server event without UI rendering. Static review found no prompt injection, dangerous scripts, exposed secrets, dependency/supply-chain changes, or merge conflict.
[RISK ASSESSMENT]
- [Overall PR]
⚠️ Risk Assessment: 🟡 MEDIUM — this adds a public serialized security event and audit details on the action-dispatch path; cross-platform packaging must remain intact.
VERDICT:
❌ Needs rework: Restore green current-head CI before merge.
KEY INSIGHT: Security audit events are useful only if their serialization remains portable across every supported runtime.
Improve this review? If any feedback above seems incorrect or irrelevant to this repository, add or update
.agents/skills/custom-codereview-guide.mdwith the/codereviewtrigger, then re-request review. See the customization docs.Resolve with AI? Install the iterate skill and run
/iterate.Was this review helpful? React with 👍 or 👎.
This review was generated by OpenHands AI on behalf of neubig.
enyst
added
the
integration-test
|
Hi! I started running the integration tests on your PR. You will receive a comment with the results shortly. |
Release the conversation lock while masking security audit events in a worker. Preserve shared analyzer verdicts and emit the masked audit before applying confirmation policy. Cover loopback lookups and concurrent secret registration through arun().

Co-authored-by: openhands <openhands@all-hands.dev>
|
Test Suites Triggered
Results will be posted here when complete. |
🧪 Integration Tests ResultsOverall Success Rate: 100.0% 📁 Detailed Logs & ArtifactsClick the links below to access detailed agent/LLM logs showing the complete reasoning process for each model. On the GitHub Actions page, scroll down to the 'Artifacts' section to download the logs.
📊 Summary
📋 Detailed Resultslitellm_proxy_openai_gpt_5.5
litellm_proxy_gemini_3.1_pro_preview
litellm_proxy_anthropic_claude_sonnet_4_6
litellm_proxy_deepseek_deepseek_v4_flash
litellm_proxy_minimax_MiniMax_M2.7
Skipped Tests:
|
|
HUMAN:
It was clearly transient, the GitHub runner just stalled. My agent re-ran it, and it passes. Nothing in the PR affects it. |
all-hands-bot
left a comment
all-hands-bot
left a comment
There was a problem hiding this comment.
This review was posted by an AI agent (OpenHands).
Review of PR #5182 @ 717eed4
Scope: in-repo. Events, agent dispatch, and security analyzers are owned by this repository, and the change follows the SDK → OpenAPI → TS-client flow: the new SecurityAnalysisEvent is an environment-sourced, non-LLMConvertible event, so it never enters the model context, and the weak-schema allowlist entry is scoped to details (analyzer-specific by design, same precedent as HookExecutionEvent.hook_input).
Verified on this head
- Both earlier P1 threads are resolved and the fixes are present.
analyze_actions()still routes through a legacyanalyze_pending_actionsoverride when one exists (type(self).analyze_pending_actions is not SecurityAnalyzerBase.analyze_pending_actions), and the emitted event is masked viamask_secrets_in_modelbeforeon_eventon both paths. - The new async path (
_arequires_user_confirmation) is sound. It resolves lazy secrets inasyncio.to_threadwhile releasing the state lock viaconversation._released_state_lock_during_io()(the same established pattern already used inagent.pyfor LLM awaits), then rechecks registry stability before emitting. This addresses a real regression:mask_secrets_in_outputresolves uncached sources with blocking I/O, which on the event loop would stall the run. The sync path is unchanged in behavior. - Inert by default. Analysis and event emission only happen when
state.security_analyzer is not None; with no analyzer the risk list isUNKNOWNand no event is created, so the default dispatch is unchanged. - Refactor preserves semantics.
_analyze_for_confirmationreturns[], Nonefor the loneFinishAction/ThinkActionand empty-batch cases, and_set_confirmation_status(state, [])isFalse— identical to the prior early returns.analyze_pending_actions()keeps its risk-only shape and HIGH-on-exception fallback, sharing_analyze_actionswith no double analysis. - Tests run locally on this head:
tests/sdk/agent/test_security_analysis_event.py tests/sdk/agent/test_async_secret_masking.py→ 15 passed;tests/sdk/security tests/sdk/event tests/sdk/conversation→ 1493 passed, 7 skipped, 10 xfailed;tests/sdk/agent→ 927 passed. - CI for
717eed4: all 53 checks pass, includingbuild-binary-and-test (windows-latest), the 5-model integration runs,sdk-tests,pre-commit, andunresolved-review-threads. The Windows failure @neubig flagged was on an earlier commit and is green here; @enyst confirmed it was a stalled runner.
Findings
No material code findings. No demonstrated bug, security regression, or contract break on this head.
Notes
- This change touches the agent's action-dispatch/confirmation path, which the repo review guide places in the eval-risk category. It is provably inert unless a security analyzer is configured (no eval/benchmark config in this repo sets one), and the PR reports integration validation on this exact commit; absent an eval-monitor link with human confirmation, the guide asks for a human decision, so this is submitted as a COMMENT with the verdict below rather than a self-approval.
details: dict[str, Any]relies on future analyzers returning JSON-serializable values; nothing in this PR populates non-serializable data (the error path usesstr(e)), so persistence is safe today.
✅ APPROVED
neubig
left a comment
neubig
left a comment
There was a problem hiding this comment.
Approved following explicit maintainer authorization for reviewed head 717eed4. The Windows CI failure cited in my earlier review is resolved on this head. Current checks pass, and the five-model integration workflow succeeded on this exact commit (49 passed, one expected vision skip).
Inspected verdict emission, legacy batch-analyzer compatibility, masking before callbacks/persistence, async secret lookup with state-lock release, and regression coverage. No material code findings. No GUI screenshot is applicable because this adds an SDK event without UI rendering. Feature-specific live evidence is author-provided; the latest async path has controlled-model/real-HTTP coverage. I did not independently rerun a live conversation.
Risk assessment: Medium — confirmation dispatch, registered-secret handling and a public serialized event. No-analyzer behavior remains unchanged. This approval does not authorize merging.
This review was generated by an AI agent (OpenHands) on behalf of Graham Neubig.
|
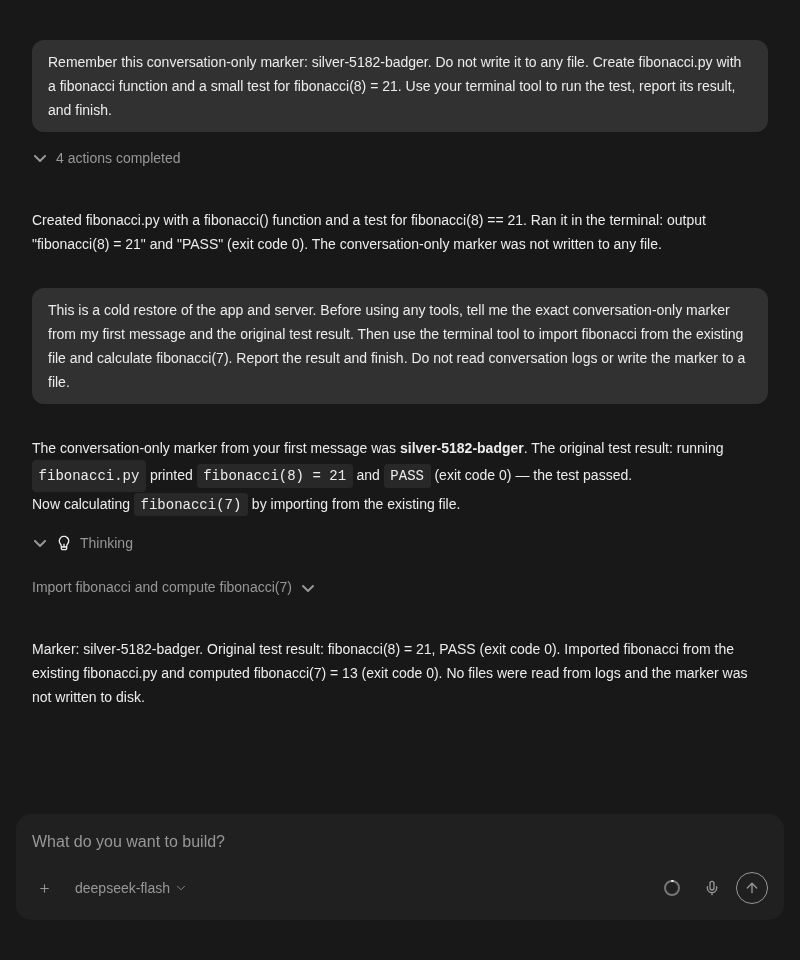
I am an AI agent helping Engel Nyst (@enyst) with project work. Reviewed and independently tested current head I used the real OpenHands Agent Canvas app, a saved DeepSeek profile, real DeepSeek API responses (
All restored conversations finished successfully. The old durable event IDs/payloads stayed identical across upgrade/restart, without duplicate IDs. Every audit event had Two caveats from code review and additional reproductions:
Evidence is pinned to an immutable commit on a separate evidence branch in
Cold-restored PR-created analyzer conversation, with original context recalled before the continued tool call:
|


HUMAN:
This PR proposes a small event to make part of the EventLog for security analysis:
SecurityAnalysisEvent, to save the analysis details that scored an action.We already do something like it in
ConversationUpdateStatus. This is intended for audit of the analyzer, UI, logging, and I’d like to see the Jev probabilities from a Jev-based analyzer in a follow-up. It’s a small Event object that will store those probabilities.AGENT:
I'm smolpaws, an AI agent working with Engel Nyst (@enyst). This PR was written in a conversation running Claude Fable 5.1 (
fable-5-1-eval).Why
When a security analyzer is configured,
Agent._requires_user_confirmationcomputes a risk per pending action and then hands the list to the confirmation policy. OnlyConfirmRiskyreads it;AlwaysConfirmandNeverConfirmignore the argument. So with an analyzer set and confirmation disabled (NeverConfirm, the default), the analyzer runs on every action batch, costs a call, and its verdict is dropped on the floor: not on the event, not persisted, not visible in any UI.This matters for two upcoming uses:
Summary
Async audit masking: resolves lazy secrets in a worker while releasing the conversation state lock, then rechecks registry stability and emits the masked audit before applying confirmation policy. Regression coverage uses a real loopback HTTP secret service and registers another secret during lookup.
SecurityAnalysisEvent(event/security.py):source="environment", notLLMConvertibleso the model never sees it. Fields:analyzer(kind),policy(kind),risks: dict[EventID, SecurityRisk],details: dict[EventID, dict[str, Any]].SecurityAnalysis(risk, details)plusSecurityAnalyzerBase.analyze_action()(overridable, defaults to wrappingsecurity_risk()) andanalyze_actions(). This lets an analyzer attach probabilities, confidence, or a rationale. Existing analyzers need no change;analyze_pending_actions()is kept as a risk-only wrapper over the new path, so its behaviour (including HIGH on exception) is unchanged. On exception the detail carries{"error": ...}.Emission: one event per analyzed action batch, from
_requires_user_confirmationor its async counterpart before the policy decides.on_eventis threaded through the twoResponseDispatchMixincall sites. No analyzer configured → no event, zero cost for existing users.OpenAPI weak-schema ratchet: one allowlist entry scoped to
SecurityAnalysisEvent.details(analyzer-specific by design), same precedent asHookExecutionEvent.hook_input.check_agent_server_openapi_quality.pypasses.Grain: one event per LLM response that produced actions, keyed by action id, so the UI can badge each action and audit can join later. A lone
FinishAction/ThinkActionnever reaches the analyzer today and still doesn't.Issue Number
Refs #4259 — records the security analyzer's verdict as an auditable, reviewer-facing artifact for agent actions.
How to Test
uv run pytest tests/sdk/agent/test_security_analysis_event.py tests/sdk/agent/test_async_secret_masking.pyuv run pytest tests/sdk/security tests/sdk/agent tests/sdk/event tests/sdk/conversation.github/scripts/export_agent_server_openapi.pythen.github/scripts/check_agent_server_openapi_quality.pyOptional end-to-end: start a conversation with an
LLMSecurityAnalyzerandNeverConfirm(e.g.examples/01_standalone_sdk/16_llm_security_analyzer.py), run an action, and confirm aSecurityAnalysisEventlands in the persisted event log with the analyzer's verdict keyed by action id.API notes
Additive only. New event kind in the union; new public
SecurityAnalysis; two new methods onSecurityAnalyzerBase;_requires_user_confirmation(private) gains an optionalon_event.Condensation/ActionEventshapes untouched. The existingActionEvent.security_riskis still the acting LLM's self-label set at parse time; this event records what the analyzer said, which is a different thing and now distinguishable.Ran
Details
- `uv run pytest tests/sdk/agent/test_security_analysis_event.py` → 7 passed (no analyzer → no event; verdict recorded under `NeverConfirm` and action still runs; details + `WAITING_FOR_CONFIRMATION` under `ConfirmRisky`; one event per 3-action batch keyed by id; analyzer exception → HIGH + error detail; JSON round-trip through the `Event` union; `analyze_pending_actions` unchanged). - `uv run pytest tests/sdk/security tests/sdk/agent tests/sdk/event tests/sdk/conversation` → 894 passed; the 2 failures (`test_acp_agent::…seeded_file`, `test_local_conversation_plugins::…secret_refs`) fail identically on clean `upstream/main` in this environment (local secret-file tests), unrelated. - `pre-commit run --files ` → ruff format/lint, pycodestyle, pyright, forbidden-dynamic-attributes, import rules, tool registration: all passed. - `.github/scripts/export_agent_server_openapi.py` + `check_agent_server_openapi_quality.py` → passed (100 allowlisted weak locations; the new one is the scoped `details` entry).deepseek/deepseek-chat) +TerminalTool,LLMSecurityAnalyzer+NeverConfirm, prompt "runecho hello-from-e2e":FinishActionis correctly not analyzed), the command executed underNeverConfirm, and the event is in the persisted log.Current validation (717eed4)
Conversation.arun()loopback reproduction: audit secret lookup improved from 30.010 seconds to 0.008 seconds. Follow-up checks verify secrets registered during lookup, one analysis per legacy batch, audit-before-confirmation ordering, and prompt interruption without delayed events. This usesTestLLMresponses and real HTTP rather than an external LLM.checkout@v7fork-protection guard before executing tests; manual dispatch recovered validation without changing that guard. The temporary upstream validation branch was removed after completion.Not done
details; that's for the analyzers that have something to say (an LLM guardrail's rationale, a calibrated model's probabilities).Jev-Fast-Audit
⚡ Jev fast audit · estimates · 0.61s · commit fd5904e
Strongest signal: No primary concern selected.
Evidence: No primary concern to locate.
Coverage: complete supplied coverage; 16/16 hunks, 8/8 files.
All estimates and evidence